
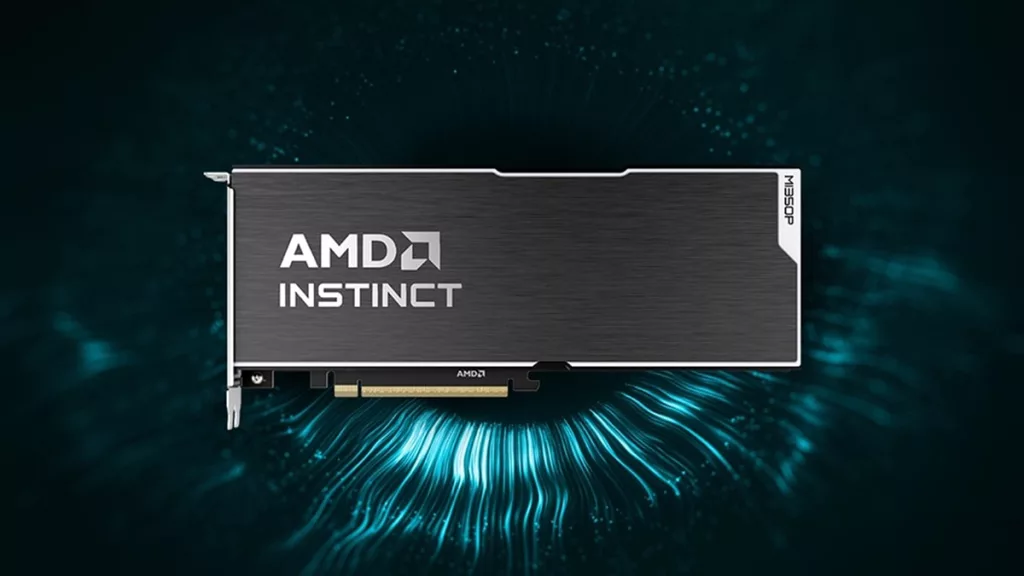
Getting CDNA 4 AI compute into a standard rack-mount server has been harder than it should be — until today. AMD has officially launched the Instinct MI350P, a PCIe add-in card based on its CDNA 4 architecture, and it’s the first Instinct GPU in this form factor in roughly four years. The pitch is simple: slot it into an existing air-cooled server, skip the Open Accelerator Module infrastructure, and start running inference workloads. AMD is clearly targeting enterprise customers who want MI350-class performance without having to rebuild their data center around it.
The MI350P is built on CDNA 4, fabricated on TSMC’s 3nm and 6nm FinFET nodes. The card carries 128 Compute Units, 8,192 Stream Processors, and 512 Matrix Cores, with a peak engine clock of 2.2 GHz. Those specs are effectively half of what AMD’s OAM-based MI350X/MI355X offer — a deliberate design choice to keep the card within PCIe power limits. Memory is 144GB of HBM3E across a 4096-bit interface at 4 TB/s peak bandwidth, plus 128MB of last-level cache with full-chip ECC. Peak performance lands at 4.6 PFLOPS at MXFP4 and 2.3 PFLOPS at MXFP8, while FP64 throughput sits at 36 TFLOPS.
AMD has rated the MI350P at 600W TBP, which happens to be the ceiling defined by the PCIe CEM specification. For servers that can’t support the full thermal load, a 450W mode is available with some performance shaved off. The card uses a 12V-2×6 power connector, making it AMD’s first Instinct product with that plug. It also uses a standard 10.5-inch dual-slot FHHL form factor, so it drops into any server that can fit eight FHHL accelerators — including systems like the Dell PowerEdge XE7740 and HPE ProLiant DL380a Gen12, both designed specifically for dense 600W-class PCIe card arrays. One trade-off worth noting: unlike the MI350X, the MI350P does not expose AMD’s Infinity Fabric scale-up links. All collective communication goes through the PCIe 5.0 x16 host interface, which delivers 128 GB/s.
The competitive context here is NVIDIA’s H200 NVL, which offers 141GB of HBM3E and runs the Hopper H200 die. AMD is claiming the MI350P is roughly 40% faster in FP16 and FP8 theoretical compute compared to the H200 NVL, though AMD-supplied theoretical comparisons always deserve the standard disclaimer about real-world delivered performance. AMD is also emphasizing ROCm open-sauce software support and no-cost development stack access as differentiators from NVIDIA’s more proprietary ecosystem.
Eight MI350P cards in a single air-cooled 2U chassis puts 1,152GB of HBM3E and 32 TB/s of aggregate memory bandwidth in one box. For inference on large open-weight models, that’s enough headroom to host a trillion-parameter model at MXFP4 in a single chassis — which is genuinely interesting for enterprises that want to run those workloads on-premises without NVLink or OAM fabric. Whether they’ll pay for it when H200 NVL hardware is still widely available in the $30-40K range is the real question. The MI350P is available now through AMD’s partner network. AMD has not publicly stated pricing.
Discussion (4 replies)
Join Discussion →more MI350P details
[URL unfurl="true"]https://www.phoronix.com/review/amd-instinct-mi350p[/URL]
[URL unfurl="true"]https://www.servethehome.com/the-amd-instinct-mi350p-is-a-hbm-pcie-accelerator-that-has-been-all-over/[/URL]
AMD unveils Helion racks for AI agents at OCP summit
CPU-only and mixed CPU/GPU configurations due from partners in November
Dan Robinson IT INFRASTRUCTURE REPORTER
Helion offers an OCP-compliant blueprint for agentic AI infrastructure built around AMD's CPUs and accelerators.
AMD launched Helios earlier this year for frontier-scale AI training and large-scale inference. Helion's enterprise configuration instead combines agent execution and inference within a single rack.
Customers can opt for a CPU-only hyperscale configuration or an enterprise configuration with a mix of CPU and GPU blades.
Depending on configuration, AMD advertises up to 32,768 of AMD's "Zen 6" CPU cores, delivered via compute nodes fitted with 256-core versions of its Venice Epyc processor, up to 16 of its Instinct MI350P GPU accelerators, and up to 102 Tbps of networking bandwidth.
The CPU-only hyperscale version offers dedicated capacity for agent execution and connections to separate model inference infrastructure, while the enterprise configuration combines agent execution, GPU inference, and supporting workloads in one rack.
Both configurations offer dense, balanced, or high-performance CPU blades. For dense deployments, EPYC 9006 chips rated at 400 W are used, while performance blades sport a version of the chip with just 96 cores but clocked at 5 GHz. Balanced blades use 256-core processors rated at 600 W.
There are also GPU inference blades, with eight Instinct MI350P GPUs in a 5U server, plus general-purpose blades, intended for database and storage servers or technical compute workloads.
https://www.theregister.com/systems...ion-racks-for-ai-agents-at-ocp-summit/5302652
AMD Instinct™ MI350P, eight GPUs in a 5U server. Two GPU servers can be added to a rack for sixteen GPUs total — two nodes of eight. The two nodes operate independently; there is no scale-up GPU fabric between them, because this configuration is designed for enterprise agentic workloads and acceleration rather than frontier-scale training.
https://www.amd.com/en/products/rackscale-solutions/helion.html
https://newsroom.amd.com/news/open-rack-blueprint-scale-agentic-ai/
imo, if this is purely inference then HBM seems like a overkill. might make sense for training use cases 🤔